
Hi Dojo - is there any way to confirm or change the amount of attempt/retries for a given file during a Midnight SYNC?
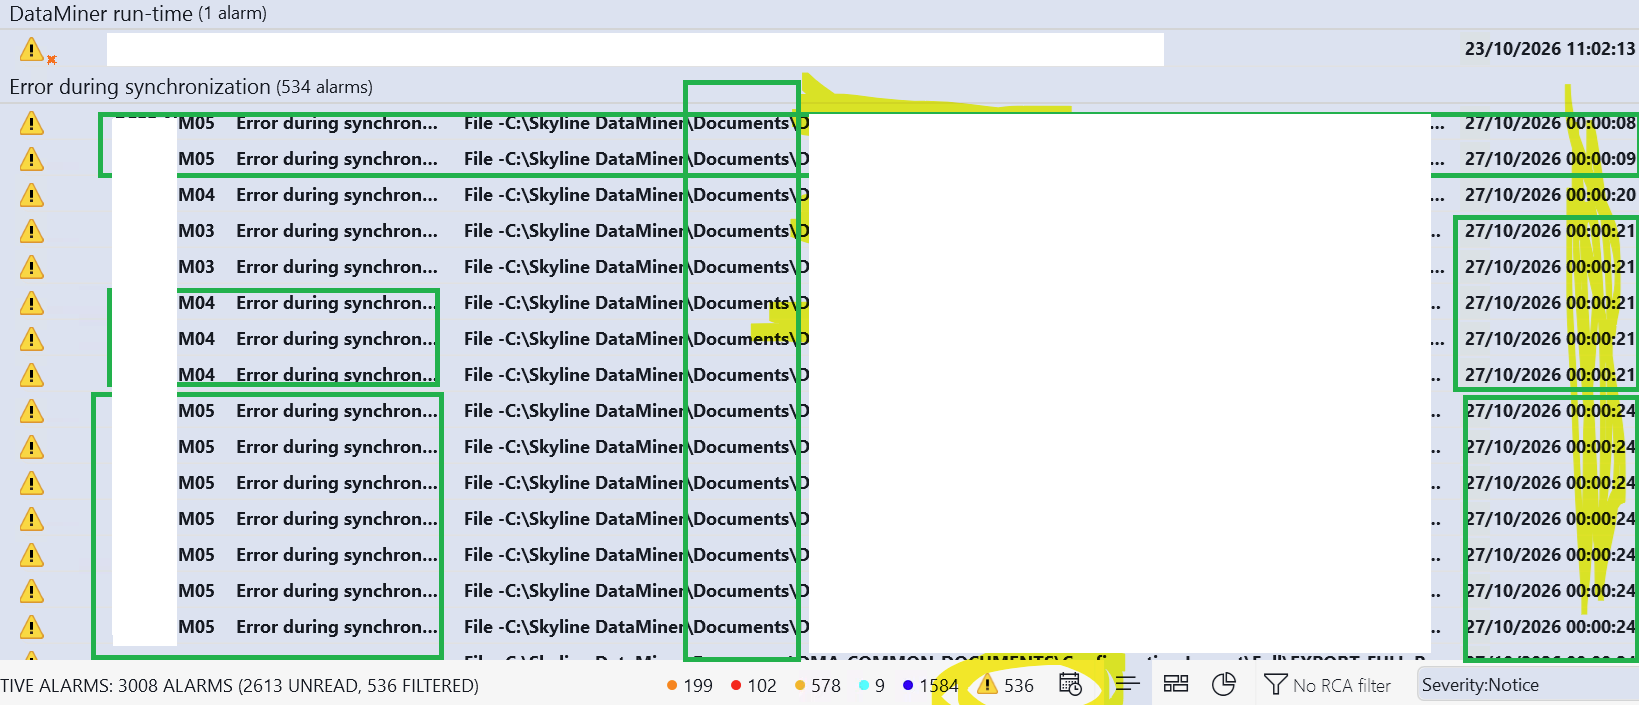
We happen to have a few files that exceed the "20MB" max limit in Documents - I understand that since the size is exceeded, the SYNC will not take place - but it is unclear why the very same file is listed multiple times in Alarm Console - any steer will be helpful

Hi,
The number of attempts cannot be changed for a midnight sync. When syncing happens, there will be a retry for the items that failed and when iterating over the different agents in the cluster it means that these attempts will happen again when trying to keep those agents also in sync with that file.
It is possible to increase the 20MB max limit of the documents in the MaintenanceSettings.xml as described here
An alternative could also be to keep a document locally when uploading it to avoid it from synchronizing, but then it is linked to a specific element.
Regards,
Hi,
During midnight synchronization, each DMA checks eligible peers (=other DMAs in the cluster) individually. Within each peer iteration, it:
– Reconciles file-change history.
– Separately scans Documents and notifies the peer about files it is missing
When the file size is too large (>20MB default), it will skip the download.
However, the missing file remains missing. Another peer notification or a later synchronization run can reach the same check and generate the warning notice again. Consequently, counts depend on which peers have the file, their change-history state, peer availability, and the number of synchronization runs. This can explain different apparent counts such as 3 and 5. There is also a separate retry queue, used, for example, when a DMA is not yet available. Therefore, 74 actual notification retries are possible, depending on how quickly the queue is processed. So it could be a combination of multiple DMA syncs and also queued retries when one DMA was not fully reachable, but that is hard to tell. To know that, one would have to do a deeper investigation to know the messages, the timestamps, which DMAs contain the file within the cluster and how they are internally registered (last file change timestamp, any size difference,…)
Thanks for the insight, Laurens
Trying to figure out why some servers try 3 times, other 5 (evidence above) for the same file: for some DMAs in PROD we noticed a 74 times retry – wondering if we have drifted due to some hotfix or any similar customization – any steer will be helpful